Activity
Mon
Wed
Fri
Sun
Nov
Dec
Jan
Feb
Mar
Apr
May
Jun
Jul
Aug
Sep
What is this?
Less
More
Build Market Close
659
5.0
Free
Lifestyle Founders Group™
13.9k
Free
Agent Empire
1.7k
Free
Easy Machine AI
4k
5.0
Free
AI Automation (A-Z)
166.2k
Free
The 1-Person Business
3.9k
Free
Claude Code Club
8.1k
4.9
$9/m
AI Money Hub
3k
5.0
$49/m
Chase AI Community
79.4k
Free
9 contributions to Clief Notes
👑
Aug 14 •
The Clief Notes AI is live 📣
It’s live. Starting today, everyone in Clief Notes has access to the new Clief Notes AI. The easiest way to use it? Don’t overthink it. Ask it the question you would normally ask me. “Where should I start?” “What should I focus on next?” “Where did you talk about [topic]?” It’ll use what’s already inside Clief Notes to help answer you and point you toward the right lesson or resource when there’s something worth going deeper on. The goal isn’t to give you another AI tool to play with. It’s to make everything already inside this community easier to actually use. If you want Access to it Comment "READY" and we'll send you access to it!

3 likes • Aug 14
Ready!
May 22 •
Bulk Data Ingestion & Synthesis Advice?
Using the frameworks + classroom materials here, I'm finally building my own Agentic OS 👏 Need to ingest a fat stack: 900+ work files (G-Drive), 700+ ChatGPT & Claude chats, iCloud mix, and a heap of meeting transcripts (docs / sheets / PDFs). Leveraging Nate Jones' OB-1 "panning-for-gold" + "heavy-file-ingestion" skills with a stage-then-route pattern. Working, but curious if anyone has battle-tested workarounds I'm missing. Specifically aiming for token-efficient pre-processing - anyone built deterministic batch summarizers that compress before pulling into Claude/Codex context? Trying to keep the OS lean on 900-file ingestion. Bonus: anyone using Obsidian Bases or Dataview for query-against-local-markdown instead of cloud DB? Any advice or suggestions appreciated!
👑
May 20 •
▶️The Foundation Module 0▶️
New lesson and Module dropped in The Foundation. Module 0.1: Where All Of This Leads. Main video is also on YouTube. 📍This is one of my favorite videos I have ever made. It pulls the whole methodology together in one sitting and showcases a few tools my team has been building on the back end. The dialogue extraction tool Kay built, the voice-controlled Claude Code setup we ran in a live call, the full content pipeline running from one folder. 📝Watch it no matter where you are in the course. If you are brand new, it shows you where this all leads. If you have been here a while, it shows you what we have been quietly building. 🔗 Module Zero is where I will place new foundational videos as time goes on as well. 0.1: Where All Of This Leads - The Foundation · Clief Notes Comments are open. Curious which part stands out most for you.
4 likes • May 20
Awesome!
👑
May 9 •
🧪 New benchmark out
New benchmark out of Meta FAIR, Stanford, and Harvard called ProgramBench. The setup: you get a compiled executable plus its docs. Source code stripped. Rebuild the program from scratch in any language you want. Tests check input/output behavior against the original binary. 200 tasks, from small CLI tools up to FFmpeg, SQLite, and the PHP interpreter. 📊 Results across 9 models: Zero tasks fully solved. Opus 4.7 was the best, passing 95% of tests on only 3% of tasks. GPT 5.4, Gemini 3.1 Pro, and Haiku 4.5 hit 0% in that bucket. The interesting part is section 5. Even the model solutions that "worked" looked nothing like the human reference. Median 1,173 lines vs 3,068 in the original. Flat directories. Fewer functions, each one longer. GPT 5.4 wrote 96% of its final code in a single turn on most tasks and never modified existing files on roughly 40% of runs. 🎯 Why it matters for us: The benchmark separates writing code from designing software. Models can produce syntax all day. They cannot yet decompose a real system into coherent modules, pick the right abstractions, or organize a codebase the way a working engineer would. That gap is what computational orchestration points at. It is also where the durable value lives. 🛠 Try it: Pick an easier task from the repo (the paper flags nnn, fzf, gron, and jq as more tractable). Run it against Claude or your model of choice. Watch where you and the model split. Note the design decisions you make that the model never even raises. Post your runs and attempts to create a harness that would allow the model to do it. Wins, failures, weird outputs, all of it. 📍 Paper and Repo: ProgramBench I'm building something on top of this right now. More soon.
0 likes • May 9
Oh hell yeah 🔥
May 9 •
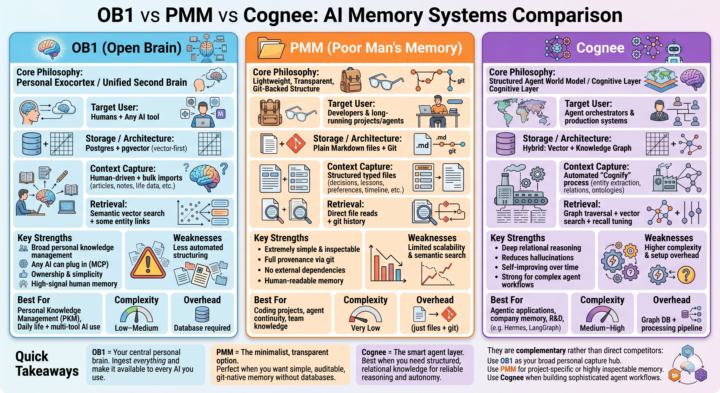
Memory management is the next frontier!
Most people are still treating LLMs like goldfish with infinite context windows. But the real power comes when you give your AI systems persistent, structured, and reliable memory. I’ve been diving deep into three distinct approaches: - Open Brain (OB1) — the personal exocortex - Poor Man’s Memory (PMM) — the ultra-lightweight, git-native path @Millenial Cat - Cognee — the structured graph + vector layer for serious agents Each represents a completely different philosophy for how we should capture, store, and retrieve context. Full breakdown dropping soon: architecture comparisons, strengths & tradeoffs, how they actually fit together in a real stack, and when I’d choose one over the others. If you’re building any kind of long-term AI workflow, personal knowledge system, or agent setup — this one’s for you.What’s your current memory strategy? Drop it below
1 like • May 9
@Daniela Capon Appreciate that! And yeah, “I’m the orchestrator, not the system” is the honest gap I’m seeing a lot of lately. To answer your question - honestly, I’m building this for me first. I run PPC operations across 140+ client accounts with a team, and the volume of context I need to move between on any given day is ridiculous lol. SOPs, automation workflows, scripts, reporting templates, prompt frameworks - it all exists but it’s not cohesive like I want it to be across tools. The custom OS is just me finally organizing the way I actually work instead of stitching things together with duct tape and good intentions. Beyond that, I’m someone who just genuinely enjoys building systems and solving problems with AI and automation. Half the things I build start as “I wonder if I could…” and then it turns into something I end up using all the time 😆 Could pieces of this become products or resources down the road? 100%. My priority at the moment is making it work for me first. Anything worth sharing I’m gonna be dropping on my website afterwards 🤘
2 likes • May 9
@Will Foster I’m finding a majority of posts in here are just golden 😆 Will be having a rabbit hole field day combing through stuff in here day over day lol
1-9 of 9

@josh-day-8576
I do marketing full-time, and sip too much Liquid Death Tea
Online now
Joined Apr 3, 2026
Denham Springs, LA
Powered by