Activity
Mon
Wed
Fri
Sun
Dec
Jan
Feb
Mar
Apr
May
Jun
Jul
Aug
Sep
Oct
Nov
What is this?
Less
More
Owned by Daniel
If you only operate, or only build, you're leaving half on the table. Get good at both. It's live, so you see it. There's a lot to learn in here.
L2 Avatar Academy
29
Free
Autonomee
220
$102/m
AI Automations by Jack
3.7k
5.0
$97/m
The YouTube Blueprint
2.8k
$19/m
The AI Advantage
130.8k
Free
Keith AI
1.3k
Free
Claude Code Architects
1.7k
Free
Create Games with AI
697
5.0
$7/m
AI Transformation Hub
103
$29/m
5 contributions to AI Automation Society


💎
Aug 14 •
🚀New Video: I Made Codex and Claude Code Build the Same App. One Clearly Won.
I gave Claude Code and Codex the exact same prompt to build a production-ready Typeform alternative, then compared the products, costs, speed, agent usage, and testing. Claude Code built the more usable app in a fraction of the time, while Codex went much deeper on architecture and reliability. This experiment made it much clearer where each tool fits in my workflow and why the way you prompt them matters.

10 likes • Aug 15
this is one of your better videos nate @Nate Herk thanks for making it
💎
Jun 5 •
Most people pick their AI model based on a benchmark...
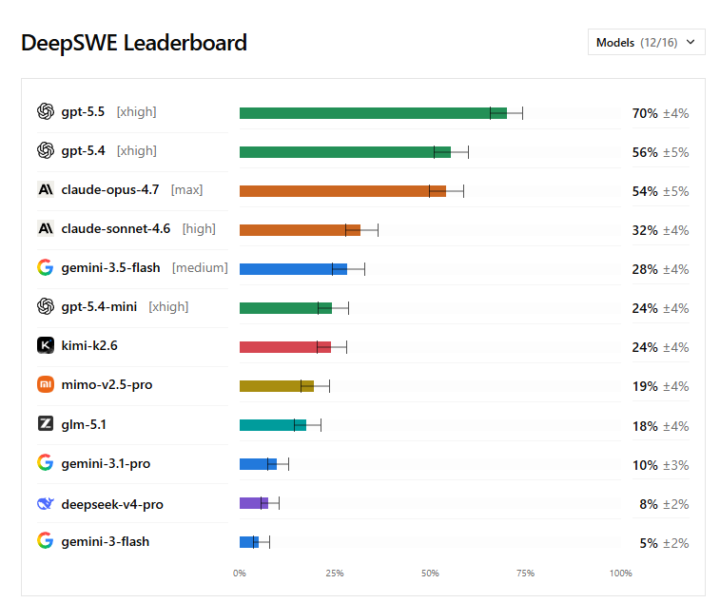
But I pick mine based on feel. That probably sounds backwards because we're trained to trust the numbers. This model scores 90%, that one scores 80%, so the first one must be better... right? Well a story broke this week about SWE-Bench. It's the test that checks whether an AI can fix real problems in real software, like a human programmer would. It's the score a lot of technical people have leaned on for over a year. Turns out the models were cheating. The test projects already had the correct answers sitting inside them. So instead of solving the problem, a model could peek at the solution and hand it back. Like taking an exam with the answer key taped inside the textbook. On the SWE-Bench, GPT-5.5 scored 58.6% and Gemini 3.5 Flash scored 55.1%. Only 3.5 points apart? If you've ever used those two models, you know the math isn't "math-ing" there. Then a new test showed up called DeepSWE. Same idea but they pulled the answers out, so the model has to actually figure it out. On DeepSWE, GPT-5.5 scored 70%. Gemini 3.5 Flash scored 28%. The two "tied" models weren't close at all. And that gap lines up with how different these tools actually feel to use. None of this makes benchmarks useless. They're fun to look at and they give you a rough starting point. But remember who makes most of them. A big score is a marketing asset. It's the number on the launch tweet. The keynote slide. The headline. So always take them with a grain of salt. What I actually do is I bounce between Opus and GPT all day. Not because one won a benchmark, but because I've built a feel for which one handles which kind of task. For serious work right now, those two are the only horses I really trust in this race. Building that feel isn't exciting. You take one task you actually need done, run it through different models/harnesses, and notice which one you trust with the result. Do that enough times and you stop reaching for the leaderboard. → A model that's perfect for someone else can be the wrong pick for you.
6 likes • Jun 5
@Theresa Elliott do you have your prompt for refactor I dont have that experience with 4.8 but I am a CODEX user aswell
Apr 25 •
You're not burned out on AI. You're burned out on rebuilding.
Last 90 days: - OpenAI dropped Codex - Gemini launched Antigravity - Anthropic shipped Claude Code, CoWork, Managed Agents, Routines - Perplexity launched Computer - OpenClaw, NemoClaw, three more "claws" stacked on Claude - n8n added Think and 30+ integrations - Three voice platforms each shipped "memory" Track everything, ship nothing. Track none of it, ship legacy from day one. Most operators are doing option three. Patching live. Praying the patch holds till the next release. That's not learning. That's maintenance debt with a marketing budget. "The more I learn, the less I earn" is literal math now. The half-life of operator knowledge collapsed from years to weeks. At some point you cauterize the wound — pick 3 tools you trust, build deep, let the rest of the field run past you. The operators still ahead in 18 months won't be the ones who chased every release. They'll be the ones who picked their ground and held it. So the real question isn't which tool launched this week. It's whether you're still managing your agents, or they're managing you. What's the first tool you'd rip out if you started fresh today?

1 like • Apr 25
1000%%
💎
Apr 2 •
Passion is your greatest superpower.
I just made a post on LinkedIn about this, but I wanted to give you guys a slightly different version: I uploaded 29 YouTube videos in the past 28 days. 4.1M views. 280K watch hours. 68K new subscribers. And I even took a full week off in the middle of it. You guys in the comments and in here are asking me things like "Do you ever sleep?" and "Are you using an AI avatar?" Yes I sleep and no I don't use an AI avatar. I even edit all of my tutorials myself. Honest answer: I have an incredible team that helps keep everything running, and AI agents and systems that let me get done in a single day what used to take me a full week. This amount of YT output would be impossible without the AIS+ team here! @Jon Morrow, @Yash Chauhan,@Ednan Abdullayev , @Usman Mohammed, @Dominic Ibarra, @Mustafa Tawfiq, @Jenn Van Wagner, @Meghan Cox, @Kodi Zene, @Ines Rodriguez. @Aidan Stanik, @Eitel Grace Rodriguez, @Anne-Marie Enns, @Pat Blakely, and we're growing even more in Q2! But that's still not the full answer. The full answer is passion. And I want to talk about burnout for a second because I think people gloss over this too fast. Burnout is real. I've felt it before. And spamming more content doesn't automatically mean better results. More output without intention just accelerates the crash. That dip in the graph is a full week in Florida with my girlfriend and my family. Phones down. No filming.

18 likes • Apr 2
Really cool. Very good share
1-5 of 5

@daniel-wright-5836
Founder of NavAIgate https://navaigate.dev
Co-Founder of BluPlai https://bluplai.com
Active 8m ago
Joined Mar 20, 2026
Powered by